This note discusses the role of the intercept in a linear regression model. It explores some key results from OLS with (and without) an intercept, before thinking through the role of an intercept in the model.
The intercept in the model (\(\beta_0\)) can be thought of as the slope parameter to a constant regressor. To keep things simple, we define this constant as the number \(\mathbf{1}\). This regressor does NOT vary across observations in the data; hence the name ‘constant’.
In Stata you have the option to estimate OLS with (default) and without (option nocons) a constant. We almost always estimate OLS with a constant; that is, we estimate an intercept parameter. However, it is helpful to explore the case without an intercept so as to understand the role of the intercept in OLS and, in particular, its relationship to the estimated residual.
OLS with an intercept
In Lecture 2 we stated the general least squares (LS) problem and solved the simple case.
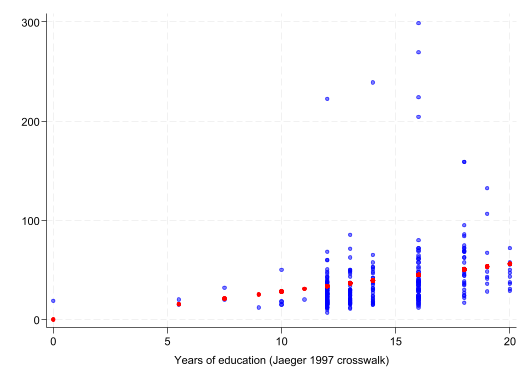
This results in a poor overall fit of the data and a residual with a non-zero mean.
De-meaning
Returning to the specification with an intercept, we solve for \(\hat{\beta}_0\) as a function of the other OLS estimators and variable means using the FOC from the LS problem:
Each variable has been de-meaned: \((y_i- \bar{y}), (x_{i1}-\bar{x}_1),\dots,(x_{ik}-\bar{x}_k)\). This tells US something about what the intercept is doing to the data: it de-means all variables. In fact, it tells us that we can solve \(\hat{\beta}_1,\dots,\hat{\beta}_k\) by first de-meaning all the variables and solving LS problem for a model without an intercept.
      Source |       SS           df       MS      Number of obs   =       300
-------------+----------------------------------   F(1, 299)       =     33.09
       Model |  38958.6637         1  38958.6637   Prob > F        =    0.0000
    Residual |   352041.64       299  1177.39679   R-squared       =    0.0996
-------------+----------------------------------   Adj R-squared   =    0.0966
       Total |  391000.304       300  1303.33435   Root MSE        =    34.313

------------------------------------------------------------------------------
  wage_tilde | Coefficient  Std. err.      t    P>|t|     [95% conf. interval]
-------------+----------------------------------------------------------------
   edu_tilde |    4.12031   .7162907     5.75   0.000     2.710701     5.52992
------------------------------------------------------------------------------
We estimate the same slope coefficient. And, if we included a constant in the regression estimation the estimate would be “machine zero”.
reg wage_tilde edu_tilde
      Source |       SS           df       MS      Number of obs   =       300
-------------+----------------------------------   F(1, 298)       =     32.98
       Model |  38958.6637         1  38958.6637   Prob > F        =    0.0000
    Residual |   352041.64       298  1181.34779   R-squared       =    0.0996
-------------+----------------------------------   Adj R-squared   =    0.0966
       Total |  391000.304       299  1307.69332   Root MSE        =    34.371

------------------------------------------------------------------------------
  wage_tilde | Coefficient  Std. err.      t    P>|t|     [95% conf. interval]
-------------+----------------------------------------------------------------
   edu_tilde |    4.12031   .7174915     5.74   0.000     2.708318    5.532302
       _cons |   1.07e-07   1.984396     0.00   1.000    -3.905204    3.905204
------------------------------------------------------------------------------
Frisch-Waugh theorem and regression on a constant
One way to rationalize what is happening is to use the Frisch-Waugh theorem. The theorem states that we can estimate a multivariate regression in two steps:
residualize \(y\) and \(x_1\) (or any chosen variable) against the other regressors
regress the residuals from these models on one another: \(\tilde{y}\) and \(\tilde{x}_1\)
In the simple case, we have a regression of
\[
y_i = \beta_0 + \beta_1 x_{1i} + u_i
\]
There are actually two variables in this regression: \(x_1\) and the constant (\(\mathbf{1}\)). Although, we do not normally talk about the constant as a regressor in this way. Regardless, we can indeed regress \(x_{1}\) and \(y\) on a constant alone.
      Source |       SS           df       MS      Number of obs   =       300
-------------+----------------------------------   F(1, 299)       =     33.09
       Model |  38958.6637         1  38958.6637   Prob > F        =    0.0000
    Residual |   352041.64       299  1177.39679   R-squared       =    0.0996
-------------+----------------------------------   Adj R-squared   =    0.0966
       Total |  391000.304       300  1303.33435   Root MSE        =    34.313

------------------------------------------------------------------------------
  wage_tilde | Coefficient  Std. err.      t    P>|t|     [95% conf. interval]
-------------+----------------------------------------------------------------
   edu_tilde |    4.12031   .7162907     5.75   0.000     2.710701     5.52992
------------------------------------------------------------------------------
We estimate the same slope coefficient as the simple bivariate case with an intercept.
The model and error term mean
The above is largely “mechanics” and a function of the OLS problem. However, there is a parallel for the model. Consider the simple linear case,
\[
Y_i = \beta_0 + \beta_1 x_i + u_i
\]
We typically make the assumption MLR 4 \(E[u_i|X_i]=0\Rightarrow E[u_i=0]\). Suppose, this wasn’t the case. Suppose, \(E[u_i|X_i] = \delta\Rightarrow E[u_i=0]=\delta\), where \(\delta\) is a non-zero constant.
What does this mean? It means that we can’t identify \(\beta_0\) unless we know \(\delta\). And, crucially, we don’t know \(\delta\) since \(u_i\) is not ‘observed’ in the data.
What do we do? Some economagic. We rewrite the error term as a deviation from its mean:
where \(\psi_0 = \beta_0 + \delta\). We have the same model (in terms of slope parameter \(\beta_1\)), but the intercept now includes the non-zero mean of the original error (\(u\)), and the new error term (\(v\)) has mean zero.
This is another way to say that we cannot separate the intercept from the non-zero mean of the error term. And, by this logic, if the model has an intercept, it is reasonable to assume that \(E[u_i]=0\).
How does this link to estimation? Well, \(n^{-1}\sum_{i=1}^n\hat{u}_i = 0\) is the sample analogue of \(E[u_i]=0\). In fact, one approach to estimation, called Methods of Moments (mentioned in Wooldridge 2025, 25), does just this: it replaces identifying moments with their sample analogue. For the linear model, our identifying moments (in the simple case) are:
\(E[u_i]=0\)
\(E[u_ix_i]=0\)
Their sample analogue are:
\(n^{-1}\sum_{i=1}^n\hat{u}_i = 0\)
\(n^{-1}\sum_{i=1}^n\hat{u}_ix_i = 0\)
where \(\hat{u}_i = y_i-\hat{\beta}_0 -\hat{\beta}_1x_i\). Substituting in this definition, you will see that (a) and (b) are just the FOCs from the LS problem.
References
Wooldridge, Jeffrey M. 2025. “Introductory Econometrics: A Modern Approach.”